higgsfield-ai/higgsfield — a trending Jupyter Notebook project
Fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters
higgsfield-ai/higgsfield — Jupyter Notebook · 4,660 stars · 869 forks · +325 today
Fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters
higgsfield - multi node training without crying
#Higgsfield is an open-source, fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters, such as Large Language Models (LLMs).

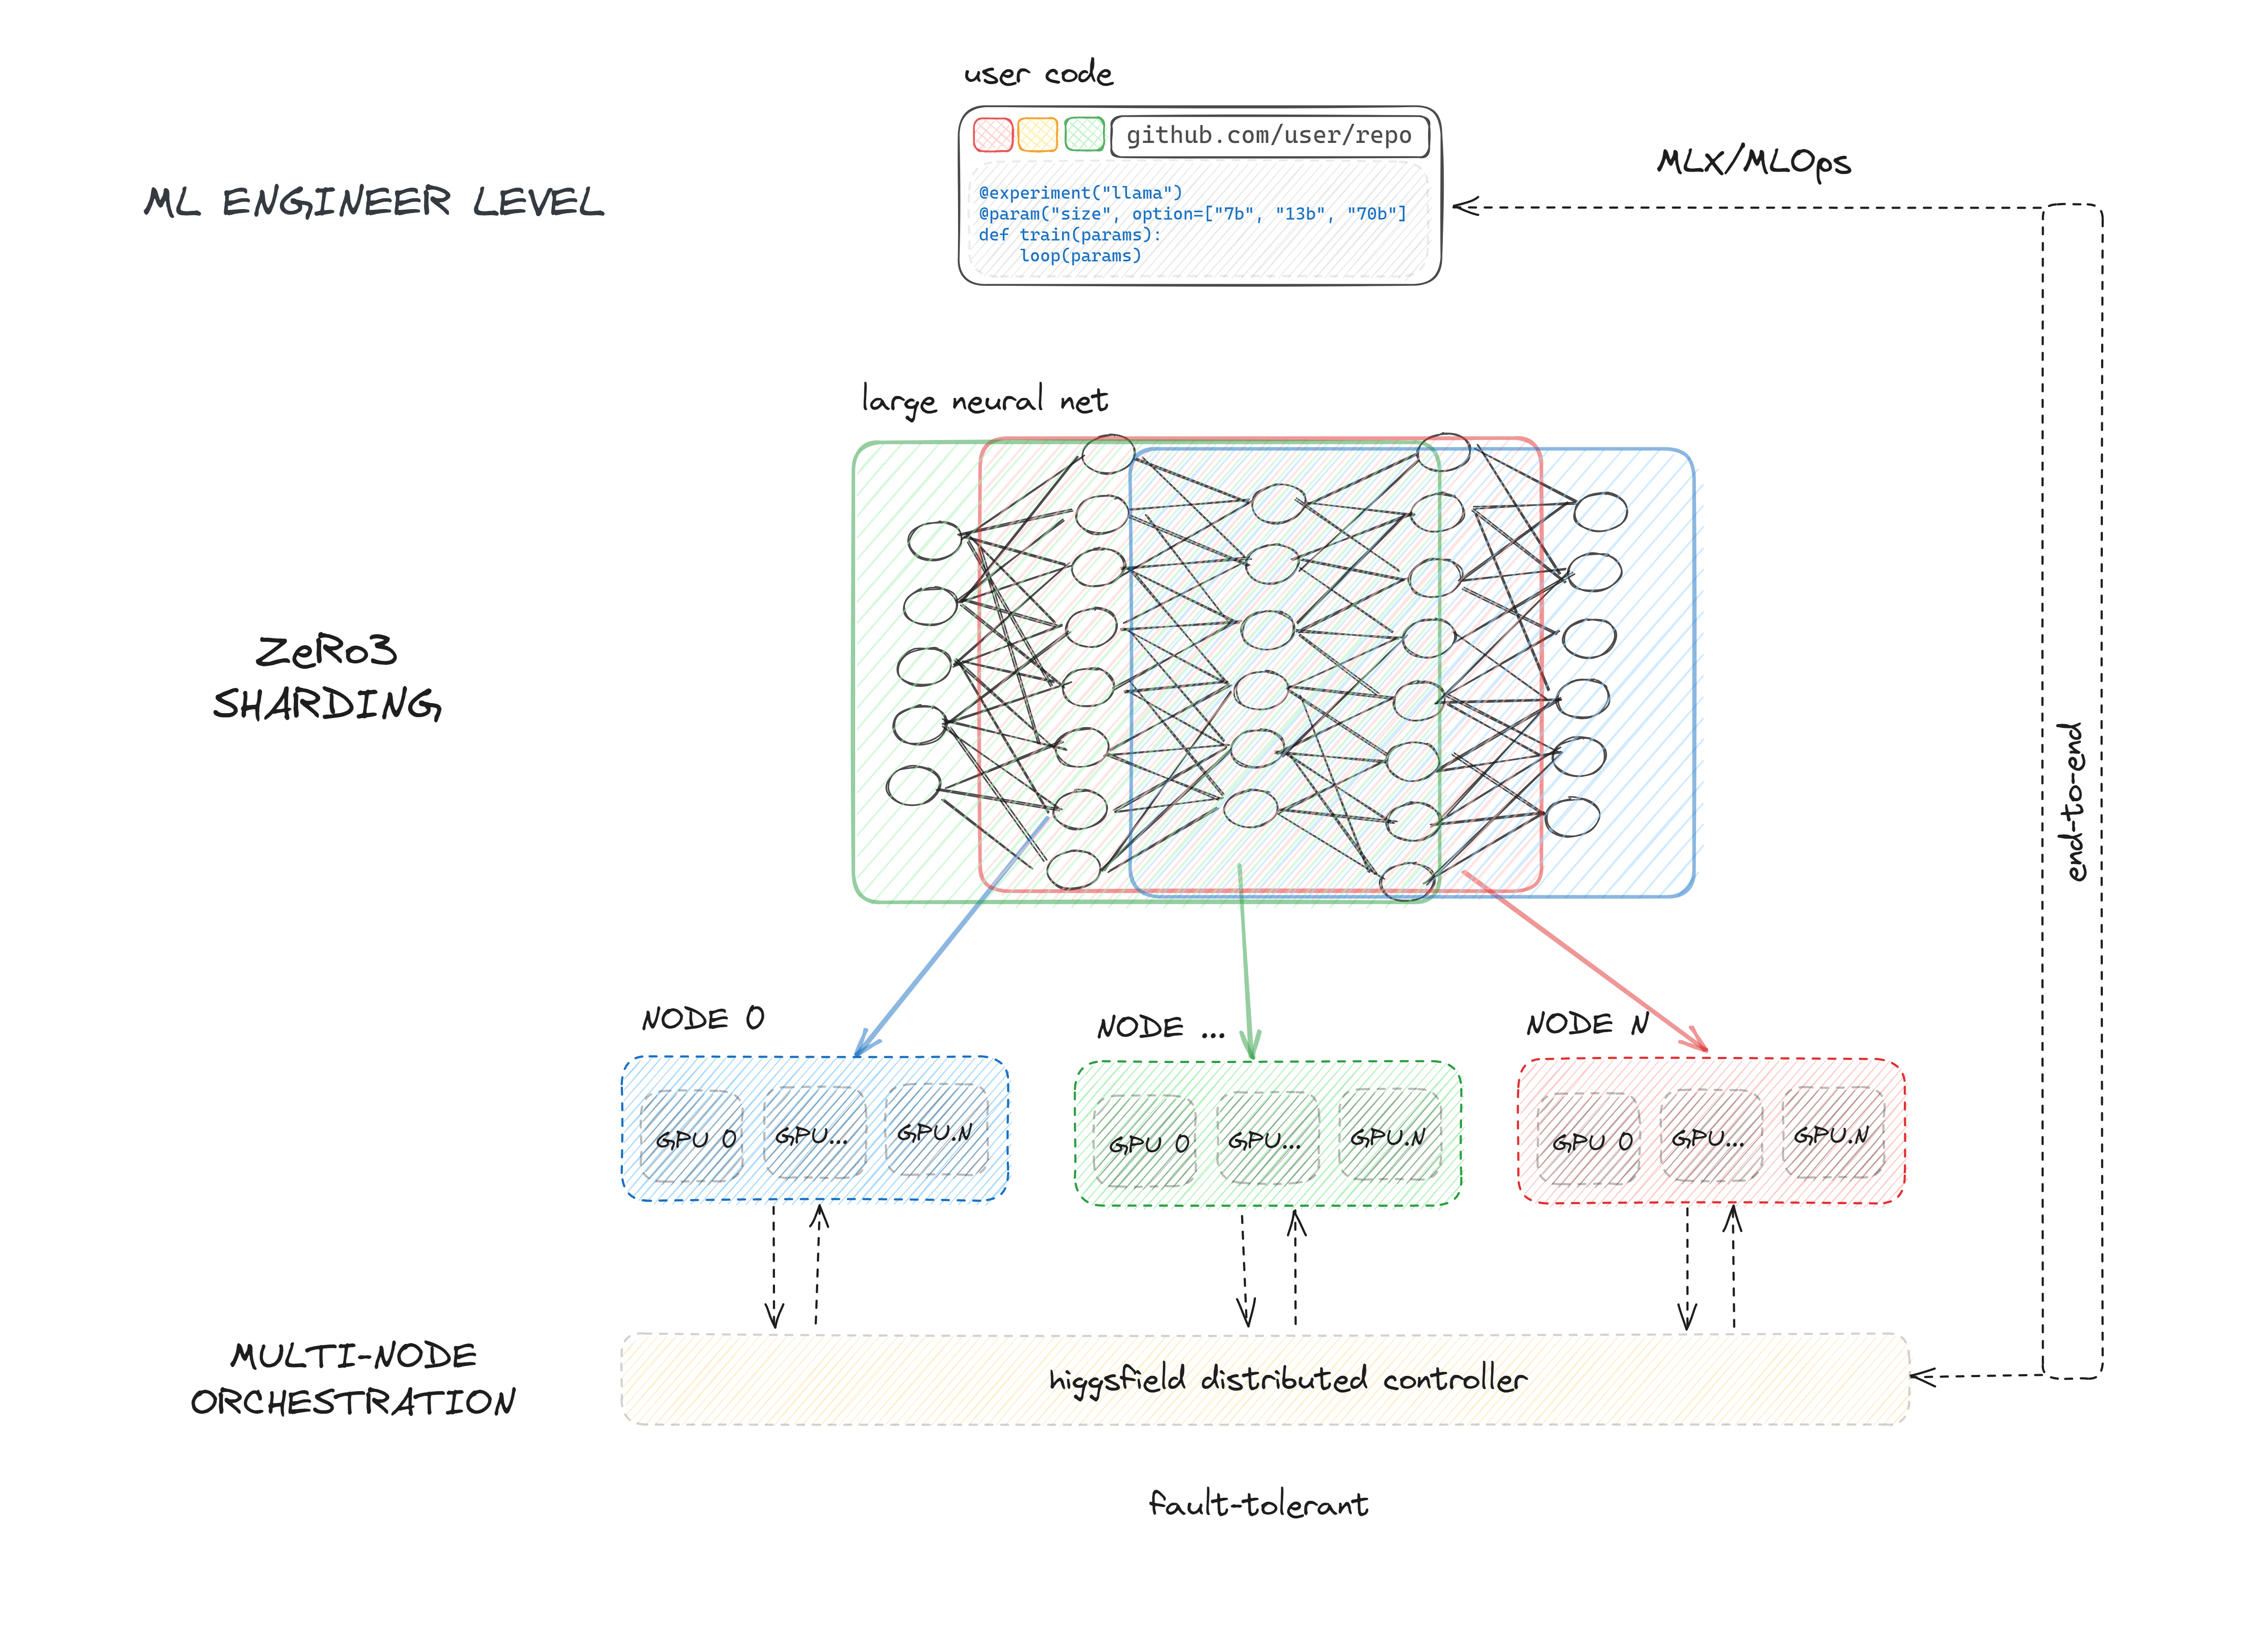
Higgsfield serves as a GPU workload manager and machine learning framework with five primary functions:
- Allocating exclusive and non-exclusive access to compute resources (nodes) to users for their training tasks.
- Supporting ZeRO-3 deepspeed API and fully sharded data parallel API of PyTorch, enabling efficient sharding for trillion-parameter models.
- Offering a framework for initiating, executing, and monitoring the training of large neural networks on allocated nodes.
- Managing resource contention by maintaining a queue for running experiments.
- Facilitating continuous integration of machine learning development through seamless integration with GitHub and GitHub Actions. Higgsfield streamlines the process of training massive models and empowers developers with a versatile and robust toolset.
Install
#$ pip install higgsfield==0.0.3
Train example
#That's all you have to do in order to train LLaMa in a distributed setting:
from higgsfield.llama import Llama70b
from higgsfield.loaders import LlamaLoader
from higgsfield.experiment import experiment

import torch.optim as optim
from alpaca import get_alpaca_data

@experiment("alpaca")
def train(params):
    model = Llama70b(zero_stage=3, fast_attn=False, precision="bf16")

    optimizer = optim.AdamW(model.parameters(), lr=1e-5, weight_decay=0.0)

    dataset = get_alpaca_data(split="train")
    train_loader = LlamaLoader(dataset, max_words=2048)

    for batch in train_loader:
        optimizer.zero_grad()
        loss = model(batch)
        loss.backward()
        optimizer.step()

    model.push_to_hub('alpaca-70b')
How it's all done?
#- We install all the required tools in your server (Docker, your project's deploy keys, higgsfield binary).
- Then we generate deploy & run workflows for your experiments.
- As soon as it gets into Github, it will automatically deploy your code on your nodes.
- Then you access your experiments' run UI through Github, which will launch experiments and save the checkpoints.
Design
#We follow the standard pytorch workflow. Thus you can incorporate anything besides what we provide, deepspeed, accelerate, or just implement your custom pytorch sharding from scratch.
Enviroment hell
No more different versions of pytorch, nvidia drivers, data processing libraries. You can easily orchestrate experiments and their environments, document and track the specific versions and configurations of all dependencies to ensure reproducibility.
Config hell
No need to define 600 arguments for your experiment. No more yaml witchcraft. You can use whatever you want, whenever you want. We just introduce a simple interface to define your experiments. We have even taken it further, now you only need to design the way to interact.
Compatibility
#We need you to have nodes with:
- Ubuntu
- SSH access
- Non-root user with sudo privileges (no-password is required)
Clouds we have tested on:
- Azure
- LambdaLabs
- FluidStack
Feel free to open an issue if you have any problems with other clouds.
Getting started
#Here you can find the quick start guide on how to setup your nodes and start training.
- Initialize the project
- Setup the environment
- Setup git
- Time to setup your nodes!
- Run your very first experiment
- Fasten your seatbelt, it's time to deploy!
Tutorial
API for common tasks in Large Language Models training.
- Working with distributed model
- Preparing Data
- Optimizing the Model Parameters
- Saving Model
- Training stabilization techniques
- Monitoring
| Platform | Purpose | Estimated Response Time | Support Level |
|---|---|---|---|
| Github Issues | Bug reports, feature requests, install issues, usage issues, etc. | < 1 day | Higgsfield Team |
| For staying up-to-date on new features. | Daily | Higgsfield Team | |
| Website | Discussion, news. | < 2 days | Higgsfield Team |
Content above is the README of higgsfield-ai/higgsfield, reproduced from GitHub’s trending list. All rights remain with the original authors.
Newsletter
New posts in your inbox. Confirm by email, unsubscribe any time.
Keep reading
Custom Web Application Development for Schools and Colleges in Nepal
How a custom web application handles attendance, terminal results, fees and parent notices for a Nepali school or college, with a clear roles table.
Tarka raj Jaishi · 7 min
What Does a Full-Stack Developer Do? A Guide for Nepali Businesses
Follow a single customer order from a phone in Tikapur to the database and back, and see what a full-stack developer handles at every step.
Tarka raj Jaishi · 6 min
vorssaint/vorssaint-utils — a trending Swift project
Free and open-source macOS menu bar toolkit.
via GitHub · 8 min
bregman-arie/devops-exercises — a trending Python project
Linux, Jenkins, AWS, SRE, Prometheus, Docker, Python, Ansible, Git, Kubernetes, Terraform, OpenStack, SQL, NoSQL, Azure, GCP, DNS, Elastic, Network, Virtualization. DevOps Interview Questions
via GitHub · 31 min
Comments
Posting as a guest