NVIDIA/Model-Optimizer — a trending Python project
A unified library of SOTA model optimization techniques like quantization, distillation, pruning, neural architecture search, speculative decoding, etc. It compresses deep learning models for downstream deployment frameworks like TensorRT-LLM, TensorRT, vLLM, etc. to optimize inference speed.
NVIDIA/Model-Optimizer — Python · 3,870 stars · 621 forks · +22 today
A unified library of SOTA model optimization techniques like quantization, distillation, pruning, neural architecture search, speculative decoding, etc. It compresses deep learning models for downstream deployment frameworks like TensorRT-LLM, TensorRT, vLLM, etc. to optimize inference speed.
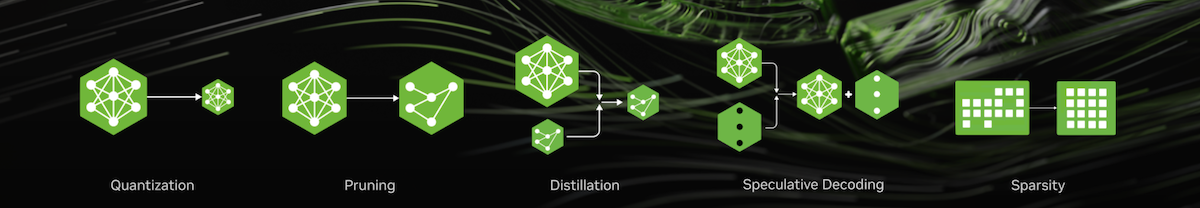


NVIDIA Model Optimizer (referred to as Model Optimizer, or ModelOpt) is a library comprising state-of-the-art model optimization techniques including quantization, pruning, Neural Architecture Search (NAS), distillation, speculative decoding and sparsity to accelerate models.
[Input] Model Optimizer currently supports inputs of a Hugging Face, PyTorch or ONNX model.
[Optimize] Model Optimizer provides Python APIs for users to easily compose the above model optimization techniques and export an optimized quantized checkpoint. Model Optimizer is also integrated with NVIDIA Megatron-Bridge, Megatron-LM and Hugging Face Accelerate for training required inference optimization techniques.
[Export for deployment] Seamlessly integrated within the NVIDIA AI software ecosystem, the quantized checkpoint generated from Model Optimizer is ready for deployment in downstream inference frameworks like SGLang, TensorRT-LLM, TensorRT, or vLLM. The unified Hugging Face export API now supports both transformers and diffusers models.
Latest News
#- [2026/09/16] End-to-end W4A4 NVFP4 + QAD tutorial for Qwen3.6-35B-A3B: NVFP4 W4A4 PTQ plus quantization-aware distillation, reaching up to 1.30x vLLM throughput over BF16 and 3.1x smaller checkpoints while recovering the accuracy W4A4 costs.
- [2026/09/09] BLOG: Improving NVFP4 Accuracy with Local-Hessian Weight Scales
- [2026/08/24] BLOG: AutoQuantize: A Fast Automatic Mixed-Precision Assignment
- [2026/08/17] BLOG: Developing Nemotron 3.5 Lightning NVFP4 with QAD Using NVIDIA Model Optimizer: Learn how quantization-aware distillation recovers accuracy from aggressive NVFP4 quantization while reducing model size and increasing throughput.
- [2026/06/26] BLOG: Creating the NVIDIA Nemotron 3 Ultra NVFP4 Checkpoint with NVIDIA Model Optimizer: How we quantized Nemotron 3 Ultra (550B) to NVFP4 with Model Optimizer — up to 5.9× higher decode-heavy inference throughput than GLM-5.1 754B FP4 while matching BF16 accuracy. NVFP4 Checkpoint on Hugging Face.
- [2026/05/27] End-to-end Optimization tutorial for Nemotron-3-Nano-30B-A3B: Pruning + two-phase distillation + FP8 quantization achieving 2.6× vLLM throughput and 2.6× memory reduction.
- [2026/05/13] Puzzletron: A new algorithm for heterogeneous pruning & NAS of LLM and VLM models.
- [2026/04/15] Customer story: Domyn compresses Colosseum-355B → 260B using ModelOpt's Minitron pruning + distillation
- [2026/03/17] Customer story: Bielik.AI builds Bielik Minitron 7B (33% smaller, 50% faster, 90% quality retained) using ModelOpt's Minitron pruning + distillation
- [2026/03/11] Model Optimizer quantized Nemotron-3-Super checkpoints are available on Hugging Face for download: FP8, NVFP4. Learn more in the Nemotron 3 Super release blog. Check out how to quantize Nemotron 3 models for deployment acceleration here
- [2026/03/11] NeMo Megatron Bridge now supports Nemotron-3-Super quantization (PTQ and QAT) and export workflows using the Model Optimizer library. See the Quantization (PTQ and QAT) guide for FP8/NVFP4 quantization and HF export instructions.
- [2025/12/11] BLOG: Top 5 AI Model Optimization Techniques for Faster, Smarter Inference
- [2025/12/08] NVIDIA TensorRT Model Optimizer is now officially rebranded as NVIDIA Model Optimizer.
- [2025/10/07] BLOG: Pruning and Distilling LLMs Using NVIDIA Model Optimizer
- [2025/09/17] BLOG: An Introduction to Speculative Decoding for Reducing Latency in AI Inference
- [2025/09/11] BLOG: How Quantization Aware Training Enables Low-Precision Accuracy Recovery
- [2025/08/29] BLOG: Fine-Tuning gpt-oss for Accuracy and Performance with Quantization Aware Training
- [2025/08/01] BLOG: Optimizing LLMs for Performance and Accuracy with Post-Training Quantization
- [2025/06/24] BLOG: Introducing NVFP4 for Efficient and Accurate Low-Precision Inference
- [2025/05/14] NVIDIA TensorRT Unlocks FP4 Image Generation for NVIDIA Blackwell GeForce RTX 50 Series GPUs
- [2025/04/21] Adobe optimized deployment using Model-Optimizer + TensorRT leading to a 60% reduction in diffusion latency, a 40% reduction in total cost of ownership
- [2025/04/05] NVIDIA Accelerates Inference on Meta Llama 4 Scout and Maverick. Check out how to quantize Llama4 for deployment acceleration here
- [2025/03/18] World's Fastest DeepSeek-R1 Inference with Blackwell FP4 & Increasing Image Generation Efficiency on Blackwell
- [2025/02/25] Model Optimizer quantized NVFP4 models available on Hugging Face for download: DeepSeek-R1-FP4, Llama-3.3-70B-Instruct-FP4, Llama-3.1-405B-Instruct-FP4
- [2025/01/28] Model Optimizer has added support for NVFP4. Check out an example of NVFP4 PTQ here.
- [2025/01/28] Model Optimizer is now open source!
- [2024/10/23] Model Optimizer quantized FP8 Llama-3.1 Instruct models available on Hugging Face for download: 8B, 70B, 405B.
- [2024/09/10] Post-Training Quantization of LLMs with NVIDIA NeMo and Model Optimizer.
- [2024/08/28] Boosting Llama 3.1 405B Performance up to 44% with Model Optimizer on NVIDIA H200 GPUs
- [2024/08/28] Up to 1.9X Higher Llama 3.1 Performance with Medusa
- [2024/08/15] New features in recent releases: Cache Diffusion, QLoRA workflow with NVIDIA NeMo, and more. Check out our blog for details.
- [2024/06/03] Model Optimizer now has an experimental feature to deploy to vLLM as part of our effort to support popular deployment frameworks. Check out the workflow here
- [2024/05/08] Announcement: Model Optimizer Now Formally Available to Further Accelerate GenAI Inference Performance
- [2024/03/27] Model Optimizer supercharges TensorRT-LLM to set MLPerf LLM inference records
- [2024/03/18] GTC Session: Optimize Generative AI Inference with Quantization in TensorRT-LLM and TensorRT
- [2024/03/07] Model Optimizer's 8-bit Post-Training Quantization enables TensorRT to accelerate Stable Diffusion to nearly 2x faster
- [2024/02/01] Speed up inference with Model Optimizer quantization techniques in TRT-LLM
Install
#To install stable release packages for Model Optimizer with pip from PyPI:
pip install -U nvidia-modelopt[all]
Model Optimizer will download and install additional third-party open source software projects. Review the license terms of these open source projects before use.
To install from source in editable mode with all development dependencies or to use the latest features, run:
# Clone the Model Optimizer repository
git clone git@github.com:NVIDIA/Model-Optimizer.git
cd Model-Optimizer

pip install -e .[dev]
You can also directly use NVIDIA container images, which have Model Optimizer pre-installed:
nvcr.io/nvidia/pytorch:<version>-py3nvcr.io/nvidia/nemo:<version>nvcr.io/nvidia/tensorrt-llm/release:<version>
Before pulling and using the container images, please review their respective license terms. Make sure to upgrade Model Optimizer to the latest version as described above. Visit our installation guide for more fine-grained control on installed dependencies or for alternative docker images and environment variables to setup.
Techniques
#| Technique | Description | Examples | Docs |
|---|---|---|---|
| Post Training Quantization | Compress model size by 2x-4x, speeding up inference while preserving model quality! | [HF LLMs / VLMs] [Megatron-Bridge LLMs / VLMs] [Diffusers] [ONNX] [Windows] | [docs] |
| Quantization Aware Training / Distillation | Refine accuracy of quantized models even further with a few training steps! | [Hugging Face] [Megatron-Bridge] | [docs] |
| Pruning | Reduce your model parameters or memory footprint and accelerate inference by removing unnecessary weights! | [General] [Megatron-Bridge] | |
| Distillation | Reduce deployment model size by teaching small models to behave like larger models! | [Hugging Face] [Megatron-Bridge] [Megatron-LM] | [docs] |
| Speculative Decoding | Train draft modules to predict extra tokens during inference! | [Hugging Face] [Megatron-LM] | [docs] |
| Sparsity | Efficiently compress your model by storing only its non-zero parameter values and their locations | [Hugging Face] | [docs] |
Pre-Quantized Checkpoints
#- Ready-to-deploy checkpoints [🤗 Hugging Face - Nvidia Model Optimizer Collection]
- Deployable on TensorRT-LLM, vLLM and SGLang
- More models coming soon!
Resources
#Model Support Matrix
#| Model Type | Support Matrix |
|---|---|
| LLM / VLM Quantization | View Support Matrix |
| Diffusers Quantization | View Support Matrix |
| ONNX Quantization | View Support Matrix |
| Windows Quantization | View Support Matrix |
| Quantization Aware Training | View Support Matrix |
| Pruning | View Support Matrix |
| Distillation | View Support Matrix |
| Speculative Decoding | View Support Matrix |
Deprecation Policy
#Model Optimizer follows a structured approach to managing deprecated features:
- Communication: Deprecation notices are documented in the Changelog. Deprecated items include source code statements indicating deprecation timing, with runtime warnings issued upon use.
- Migration Period: Since Model Optimizer is still pre-1.0, we provide a 1-release (~1-month) migration period after deprecation. During this window, deprecated features continue functioning while issuing warnings.
- Scope: The policy addresses both complete deprecations (entire APIs removed) and partial ones (specific parameters removed while methods remain).
- Removal: Following the migration period, deprecated elements are removed in alignment with semantic versioning standards, potentially including breaking changes in minor version updates while Model Optimizer remains in 0.x.
Citation
#If you use NVIDIA Model Optimizer in your research, please cite it as follows:
@misc{nvidia-modelopt,
  author       = {{NVIDIA Corporation}},
  title        = {{NVIDIA Model Optimizer}},
  howpublished = {\url{https://github.com/NVIDIA/Model-Optimizer}},
  year         = {2024--2026},
  note         = {GitHub repository}
}
Contributing
#Model Optimizer is now open source! We welcome any feedback, feature requests and PRs. Please read our Contributing guidelines for details on how to contribute to this project.
AI Agents
#ModelOpt's agent skills can be installed from this repository and used in any workspace.
Claude Code
#claude plugin marketplace add https://github.com/NVIDIA/Model-Optimizer.git
claude plugin install modelopt@modelopt
Codex
#codex plugin marketplace add https://github.com/NVIDIA/Model-Optimizer.git
Then open /plugins, select the modelopt marketplace, and install modelopt.
Contributors can also use the skills directly from a checkout. See the
agent tooling notes.
Top Contributors
#Happy optimizing!
Content above is the README of NVIDIA/Model-Optimizer, reproduced from GitHub’s trending list. All rights remain with the original authors.
Newsletter
New posts in your inbox. Confirm by email, unsubscribe any time.
More in Python
View allbregman-arie/devops-exercises — a trending Python project
Linux, Jenkins, AWS, SRE, Prometheus, Docker, Python, Ansible, Git, Kubernetes, Terraform, OpenStack, SQL, NoSQL, Azure, GCP, DNS, Elastic, Network, Virtualization. DevOps Interview Questions
via GitHub · 31 min
HKUDS/DeepTutor — a trending Python project
DeepTutor: Lifelong Personalized Tutoring. https://deeptutor.info/ .
via GitHub · 14 min
NVIDIA/SkillSpector — a trending Python project
Security scanner for AI agent skills. Detect vulnerabilities, malicious patterns, security risks, prompt injection, data exfiltration, and supply-chain risks in Claude Code, Codex, and MCP skills before you install them.
via GitHub · 2 min
AgriciDaniel/claude-seo — a trending Python project
Universal SEO skill for Claude Code. 26 sub-skills + 19 sub-agents covering technical SEO, E-E-A-T, schema, GEO/AEO, agent readiness (Lighthouse Agentic Browsing, WebMCP, llms.txt), backlinks, local SEO, e-commerce, international SEO, Google APIs, and PDF/Excel reporting. 9 optional extensions for l
via GitHub · 6 min
Comments
Posting as a guest